LemonadaCore · What we deliver
AI model optimization: quality, latency and cost
Improve an AI application against measurable business goals, using evaluations before changing prompts or models.
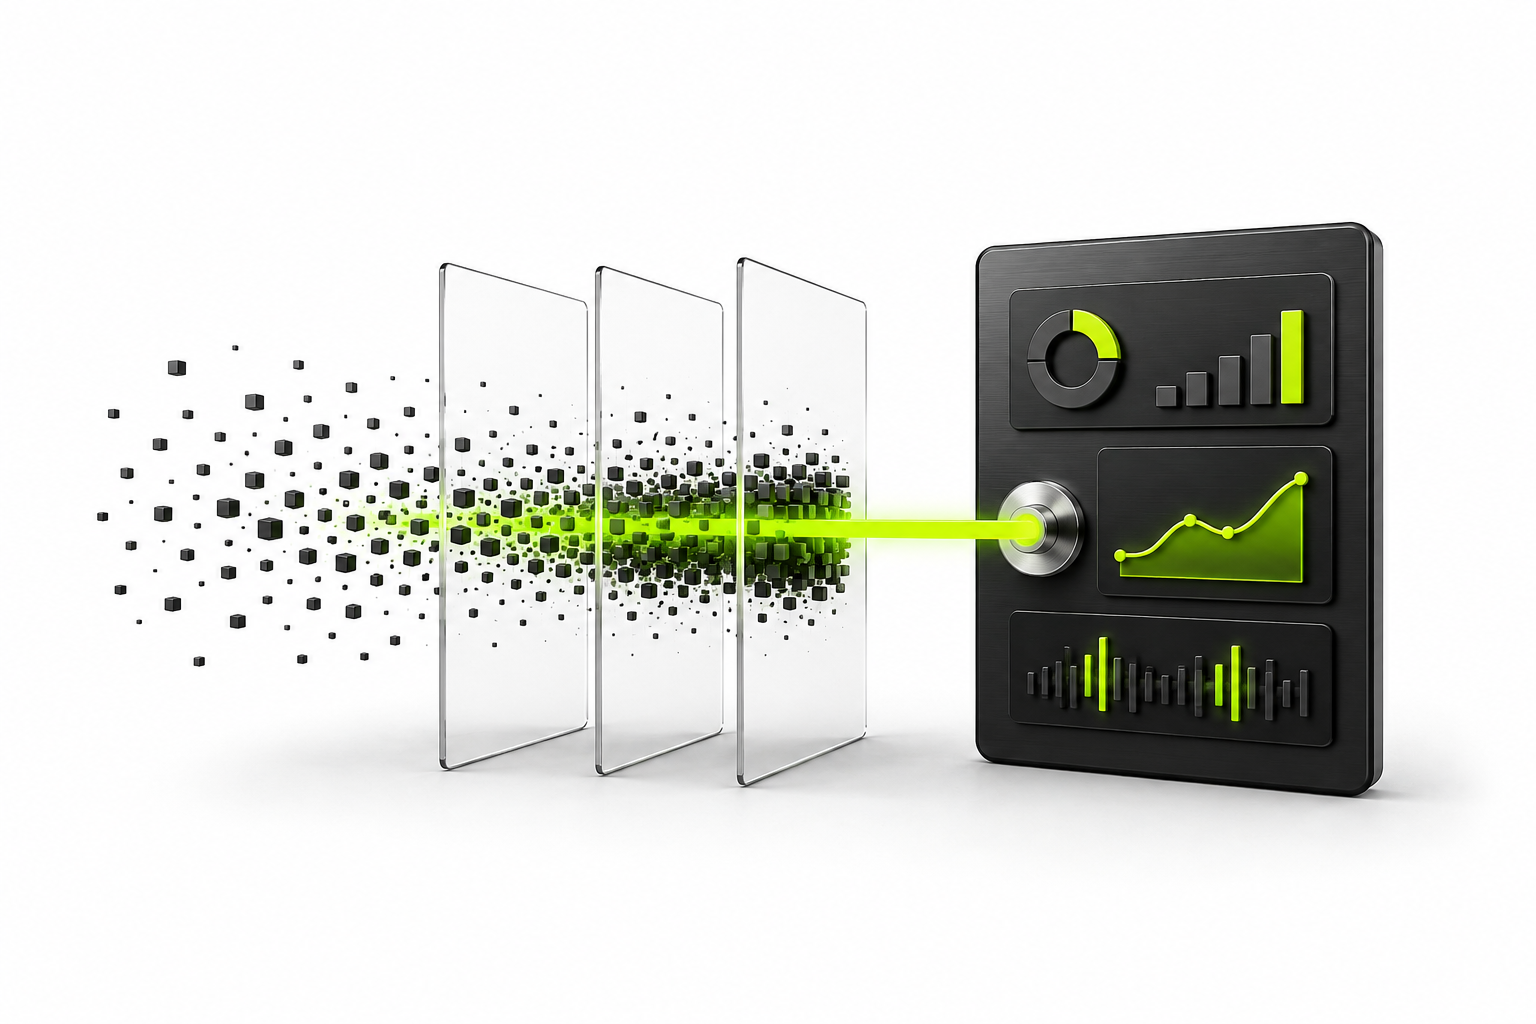
Measure before optimizing
We build an evaluation set from representative tasks and failure cases. Quality, response time and cost are measured together so an apparent saving does not hide a worse user experience.
Choose the right intervention
We compare prompt design, retrieval quality, caching, model routing and smaller models. Fine-tuning is considered when the data and task justify it, rather than treated as a default requirement.
Validate and monitor
Candidate changes are checked against a baseline, including regressions and unusual inputs. We document trade-offs and monitor the chosen approach after release. Performance improvements depend on the starting system and workload.
Frequently asked questions
How does a project start?
We review your use case, inputs and constraints, then agree on deliverables, acceptance criteria and a proposal.
Can you work with our existing setup?
Yes. We first assess the current tools, access and code or data, then propose the changes needed.